%52%65%69%6e%66%6f%72%63%65%6d%65%6e%74
-
 KAIST Develops AI That Generates Feasible Plans for Delivery, Production, and Workforce Scheduling
From parcel delivery routes and factory production schedules to hospital duty rosters, many real-world planning tasks require solutions that satisfy numerous operational constraints. KAIST researchers have developed an artificial intelligence technique that can independently generate feasible plans satisfying all constraints specified in a mathematical optimization problem.
KAIST (President Choongsik Bae) announced on August 3 that a research team led by Professor Min-Soo Kim from the School of Computing has developed RL-SPH (Reinforcement Learning-based Start Primal Heuristic), a reinforcement learning technique that trains AI to independently produce feasible plans without relying on an external solver.
The key feature of the technology is its ability to learn how to produce solutions that satisfy the multiple constraints encoded in an optimization problem. The research team expects the method to serve as an important foundation for AI-based decision-making in fields including logistics, manufacturing, semiconductor production, and workforce management.
Parcel delivery routing, vehicle routing, factory production scheduling, and hospital staff rostering are representative planning problems that can be formulated using integer linear programming, or ILP. ILP is a mathematical optimization technique for finding the most efficient solution while satisfying a set of linear constraints and requiring some or all decision variables to take integer values.
A parcel delivery plan, for example, must do more than simply minimize delivery time. It must also comply with vehicle capacity limits and driver working-hour requirements while ensuring that every destination is visited. A route that violates even one of these conditions cannot be used in practice, regardless of how short or inexpensive it may appear.
Existing learning-based approaches can rapidly generate approximate or partial solutions, but these predictions frequently violate constraints. Consequently, many approaches pass their outputs to specialized ILP solvers, such as Gurobi or SCIP, which are then responsible for obtaining a feasible solution. The paper notes that existing end-to-end learning-based primal heuristics generally struggle to generate feasible solutions independently.
RL-SPH addresses this limitation by iteratively revising a candidate solution rather than attempting to predict the final answer in a single step. At each stage, it selects multiple decision variables that are likely to improve feasibility and determines whether their values should be increased, decreased, or left unchanged. The model then learns from the resulting changes in constraint violations and solution quality.
Notably, the team designed the AI to first find a plan that is actually usable, rather than the single best plan. The overall procedure consists of two stages. In the first stage, the AI prioritizes finding an initial feasible solution that satisfies all constraints. In the second stage, it seeks a higher-quality solution by reducing the objective value, such as cost or processing time, while maintaining feasibility.
For example, in a factory production-planning problem, the method would first identify a schedule that satisfies requirements such as delivery deadlines, equipment capacity, and available labor. It would then attempt to reduce production cost and time without violating those conditions. The research therefore prioritizes finding a plan that can actually be implemented before attempting to optimize it further.
The team also introduced ILP-GT, a new AI model that learns the relationships between variables and constraints, along with a feasibility-aware search strategy that prioritizes revising the variables most effective for resolving the problem, substantially improving computational efficiency.
Across five representative benchmarks, RL-SPH achieved a 100% feasibility rate, successfully finding a usable plan for every problem. It maintained the same performance even on more complex problems involving general (non-binary) integer variables.
Compared with existing techniques, RL-SPH reduced the primal gap — the gap between a method's solution and the best-known solution — by an average of 28.6 times, and improved the primal integral — a measure of the speed and quality of the search process — by 2.6 times. The time needed to find the first feasible plan was also 2.5 times faster on average.
Among recent AI techniques such as PAS, DDIM, and DiffILO, RL-SPH was the only method to achieve a 100% feasibility rate across three benchmarks compared (SC, CA, IS). Its training also took an average of just 30 minutes — 14.7 times faster than existing techniques and roughly 34 times faster than the most recent unsupervised learning — an AI training method that finds patterns in data without being given the correct answers in advance — based technique.
The technique further demonstrated its generalization potential on MIPLIB, an international benchmark library for mixed-integer programming widely used in academia and industry. It reliably found feasible plans not only for problems up to 67 times larger than those it was trained on, but also for entirely new problem types it had never encountered during training.
“In real-world applications, a plan that can actually be implemented is often more important than a theoretically optimal answer that violates practical constraints,” said Professor Kim.
He added, “This research demonstrates that AI can learn to generate feasible solutions without relying on a specialized optimization solver to enforce feasibility. We expect the technology to provide an important foundation for AI-based decision-making in logistics, manufacturing, semiconductor production, workforce management, and other industrial fields.”
Tae-Hoon Lee, a doctoral student in the KAIST School of Computing, participated as the first author, and Professor Min-Soo Kim led the research.
The findings were presented at the 43rd International Conference on Machine Learning, or ICML 2026, held in Seoul from July 6 to 11. ICML is regarded as one of the world’s premier international conferences in machine learning.
Paper title: RL-SPH: Learning to Achieve Feasible Solutions for Integer Linear Programs
DOI: https://doi.org/10.48550/arXiv.2411.19517
Authors: Tae-Hoon Lee (KAIST, first author), Min-Soo Kim (KAIST, corresponding author)
This research was supported by the Ministry of Science and ICT and the Institute of Information & Communications Technology Planning & Evaluation through related software research and Information Technology Research Center programs, as well as by the National Research Foundation of Korea. The paper’s acknowledgements specifically identify NRF and IITP support, including an ITRC grant.
2026.08.03 View 1161
-
 KAIST debuts “DreamWaQer” - a quadrupedal robot that can walk in the dark
- The team led by Professor Hyun Myung of the School of Electrical Engineering developed “DreamWaQ”, a deep reinforcement learning-based walking robot control technology that can walk in an atypical environment without visual and/or tactile information
- Utilization of “DreamWaQ” technology can enable mass production of various types of “DreamWaQers”
- Expected to be used in exploration of atypical environment involving unique circumstances such as disasters by fire.
A team of Korean engineering researchers has developed a quadrupedal robot technology that can climb up and down the steps and moves without falling over in uneven environments such as tree roots without the help of visual or tactile sensors even in disastrous situations in which visual confirmation is impeded due to darkness or thick smoke from the flames.
KAIST (President Kwang Hyung Lee) announced on the 29th of March that Professor Hyun Myung's research team at the Urban Robotics Lab in the School of Electrical Engineering developed a walking robot control technology that enables robust 'blind locomotion' in various atypical environments.
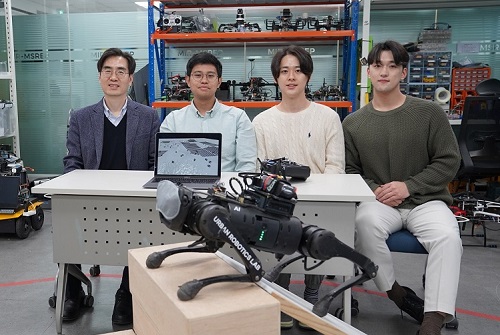
< (From left) Prof. Hyun Myung, Doctoral Candidates I Made Aswin Nahrendra, Byeongho Yu, and Minho Oh. In the foreground is the DreamWaQer, a quadrupedal robot equipped with DreamWaQ technology. >
The KAIST research team developed "DreamWaQ" technology, which was named so as it enables walking robots to move about even in the dark, just as a person can walk without visual help fresh out of bed and going to the bathroom in the dark. With this technology installed atop any legged robots, it will be possible to create various types of "DreamWaQers".
Existing walking robot controllers are based on kinematics and/or dynamics models. This is expressed as a model-based control method. In particular, on atypical environments like the open, uneven fields, it is necessary to obtain the feature information of the terrain more quickly in order to maintain stability as it walks. However, it has been shown to depend heavily on the cognitive ability to survey the surrounding environment.
In contrast, the controller developed by Professor Hyun Myung's research team based on deep reinforcement learning (RL) methods can quickly calculate appropriate control commands for each motor of the walking robot through data of various environments obtained from the simulator. Whereas the existing controllers that learned from simulations required a separate re-orchestration to make it work with an actual robot, this controller developed by the research team is expected to be easily applied to various walking robots because it does not require an additional tuning process.
DreamWaQ, the controller developed by the research team, is largely composed of a context estimation network that estimates the ground and robot information and a policy network that computes control commands. The context-aided estimator network estimates the ground information implicitly and the robot’s status explicitly through inertial information and joint information. This information is fed into the policy network to be used to generate optimal control commands. Both networks are learned together in the simulation.
While the context-aided estimator network is learned through supervised learning, the policy network is learned through an actor-critic architecture, a deep RL methodology. The actor network can only implicitly infer surrounding terrain information. In the simulation, the surrounding terrain information is known, and the critic, or the value network, that has the exact terrain information evaluates the policy of the actor network.
This whole learning process takes only about an hour in a GPU-enabled PC, and the actual robot is equipped with only the network of learned actors. Without looking at the surrounding terrain, it goes through the process of imagining which environment is similar to one of the various environments learned in the simulation using only the inertial sensor (IMU) inside the robot and the measurement of joint angles. If it suddenly encounters an offset, such as a staircase, it will not know until its foot touches the step, but it will quickly draw up terrain information the moment its foot touches the surface. Then the control command suitable for the estimated terrain information is transmitted to each motor, enabling rapidly adapted walking.
The DreamWaQer robot walked not only in the laboratory environment, but also in an outdoor environment around the campus with many curbs and speed bumps, and over a field with many tree roots and gravel, demonstrating its abilities by overcoming a staircase with a difference of a height that is two-thirds of its body. In addition, regardless of the environment, the research team confirmed that it was capable of stable walking ranging from a slow speed of 0.3 m/s to a rather fast speed of 1.0 m/s.
The results of this study were produced by a student in doctorate course, I Made Aswin Nahrendra, as the first author, and his colleague Byeongho Yu as a co-author. It has been accepted to be presented at the upcoming IEEE International Conference on Robotics and Automation (ICRA) scheduled to be held in London at the end of May. (Paper title: DreamWaQ: Learning Robust Quadrupedal Locomotion With Implicit Terrain Imagination via Deep Reinforcement Learning)
The videos of the walking robot DreamWaQer equipped with the developed DreamWaQ can be found at the address below.
Main Introduction: https://youtu.be/JC1_bnTxPiQ Experiment Sketches: https://youtu.be/mhUUZVbeDA0
Meanwhile, this research was carried out with the support from the Robot Industry Core Technology Development Program of the Ministry of Trade, Industry and Energy (MOTIE). (Task title: Development of Mobile Intelligence SW for Autonomous Navigation of Legged Robots in Dynamic and Atypical Environments for Real Application)
< Figure 1. Overview of DreamWaQ, a controller developed by this research team. This network consists of an estimator network that learns implicit and explicit estimates together, a policy network that acts as a controller, and a value network that provides guides to the policies during training. When implemented in a real robot, only the estimator and policy network are used. Both networks run in less than 1 ms on the robot's on-board computer. >
< Figure 2. Since the estimator can implicitly estimate the ground information as the foot touches the surface, it is possible to adapt quickly to rapidly changing ground conditions. >
< Figure 3. Results showing that even a small walking robot was able to overcome steps with height differences of about 20cm. >
2023.05.18 View 21382
-
 KAIST’s Robo-Dog “RaiBo” runs through the sandy beach
KAIST (President Kwang Hyung Lee) announced on the 25th that a research team led by Professor Jemin Hwangbo of the Department of Mechanical Engineering developed a quadrupedal robot control technology that can walk robustly with agility even in deformable terrain such as sandy beach.
< Photo. RAI Lab Team with Professor Hwangbo in the middle of the back row. >
Professor Hwangbo's research team developed a technology to model the force received by a walking robot on the ground made of granular materials such as sand and simulate it via a quadrupedal robot. Also, the team worked on an artificial neural network structure which is suitable in making real-time decisions needed in adapting to various types of ground without prior information while walking at the same time and applied it on to reinforcement learning. The trained neural network controller is expected to expand the scope of application of quadrupedal walking robots by proving its robustness in changing terrain, such as the ability to move in high-speed even on a sandy beach and walk and turn on soft grounds like an air mattress without losing balance.
This research, with Ph.D. Student Soo-Young Choi of KAIST Department of Mechanical Engineering as the first author, was published in January in the “Science Robotics”. (Paper title: Learning quadrupedal locomotion on deformable terrain).
Reinforcement learning is an AI learning method used to create a machine that collects data on the results of various actions in an arbitrary situation and utilizes that set of data to perform a task. Because the amount of data required for reinforcement learning is so vast, a method of collecting data through simulations that approximates physical phenomena in the real environment is widely used.
In particular, learning-based controllers in the field of walking robots have been applied to real environments after learning through data collected in simulations to successfully perform walking controls in various terrains.
However, since the performance of the learning-based controller rapidly decreases when the actual environment has any discrepancy from the learned simulation environment, it is important to implement an environment similar to the real one in the data collection stage. Therefore, in order to create a learning-based controller that can maintain balance in a deforming terrain, the simulator must provide a similar contact experience.
The research team defined a contact model that predicted the force generated upon contact from the motion dynamics of a walking body based on a ground reaction force model that considered the additional mass effect of granular media defined in previous studies.
Furthermore, by calculating the force generated from one or several contacts at each time step, the deforming terrain was efficiently simulated.
The research team also introduced an artificial neural network structure that implicitly predicts ground characteristics by using a recurrent neural network that analyzes time-series data from the robot's sensors.
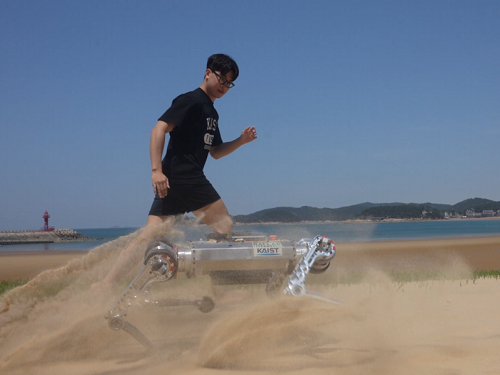
The learned controller was mounted on the robot 'RaiBo', which was built hands-on by the research team to show high-speed walking of up to 3.03 m/s on a sandy beach where the robot's feet were completely submerged in the sand. Even when applied to harder grounds, such as grassy fields, and a running track, it was able to run stably by adapting to the characteristics of the ground without any additional programming or revision to the controlling algorithm.
In addition, it rotated with stability at 1.54 rad/s (approximately 90° per second) on an air mattress and demonstrated its quick adaptability even in the situation in which the terrain suddenly turned soft.
The research team demonstrated the importance of providing a suitable contact experience during the learning process by comparison with a controller that assumed the ground to be rigid, and proved that the proposed recurrent neural network modifies the controller's walking method according to the ground properties.
The simulation and learning methodology developed by the research team is expected to contribute to robots performing practical tasks as it expands the range of terrains that various walking robots can operate on.
The first author, Suyoung Choi, said, “It has been shown that providing a learning-based controller with a close contact experience with real deforming ground is essential for application to deforming terrain.” He went on to add that “The proposed controller can be used without prior information on the terrain, so it can be applied to various robot walking studies.”
This research was carried out with the support of the Samsung Research Funding & Incubation Center of Samsung Electronics.
< Figure 1. Adaptability of the proposed controller to various ground environments. The controller learned from a wide range of randomized granular media simulations showed adaptability to various natural and artificial terrains, and demonstrated high-speed walking ability and energy efficiency. >
< Figure 2. Contact model definition for simulation of granular substrates. The research team used a model that considered the additional mass effect for the vertical force and a Coulomb friction model for the horizontal direction while approximating the contact with the granular medium as occurring at a point. Furthermore, a model that simulates the ground resistance that can occur on the side of the foot was introduced and used for simulation. >
2023.01.26 View 28506
-
 Prof. Sang Wan Lee Selected for 2021 IBM Academic Award
Professor Sang Wan Lee from the Department of Bio and Brain Engineering was selected as the recipient of the 2021 IBM Global University Program Academic Award. The award recognizes individual faculty members whose emerging science and technology contains significant interest for universities and IBM.
Professor Lee, whose research focuses on artificial intelligence and computational neuroscience, won the award for his research proposal titled A Neuroscience-Inspired Approach for Metacognitive Reinforcement Learning. IBM provides a gift of $40,000 to the recipient’s institution in recognition of the selection of the project but not as a contract for services.
Professor Lee’s project aims to exploit the unique characteristics of human reinforcement learning. Specifically, he plans to examines the hypothesis that metacognition, a human’s ability to estimate their uncertainty level, serves to guide sample-efficient and near-optimal exploration, making it possible to achieve an optimal balance between model-based and model-free reinforcement learning.
He was also selected as the winner of the Google Research Award in 2016 and has been working with DeepMind and University College London to conduct basic research on decision-making brain science to establish a theory on frontal lobe meta-enhance learning.
"We plan to conduct joint research for utilizing brain-based artificial intelligence technology and frontal lobe meta-enhanced learning technology modeling in collaboration with an international research team including IBM, DeepMind, MIT, and Oxford,” Professor Lee said.
2021.06.25 View 22578